

What gets recorded
Recording happens per provider attempt, not per request. A request that falls back twice before succeeding produces three recordings, each with its own body pair, so you can see how the conversation was reshaped for each provider. An Autofix retry is its own attempt too, which is how you compare the request that failed against the patched one that worked.
A request Manifest blocked itself, on a hard limit or a malformed body, still lists one attempt, labelled with the model you asked for or No provider. It carries the failure status and no Messages, Tools, or Raw tab: Manifest sent nothing to a provider, so there is nothing to read back.
Reading it back
Open a request in the dashboard’s Requests page and pick an attempt in the Attempts list. The initial call, each fallback, and an Autofix retry are separate attempts, and each one shows its own conversation. The Messages, Tools, and Raw tabs appear when that attempt has a recording.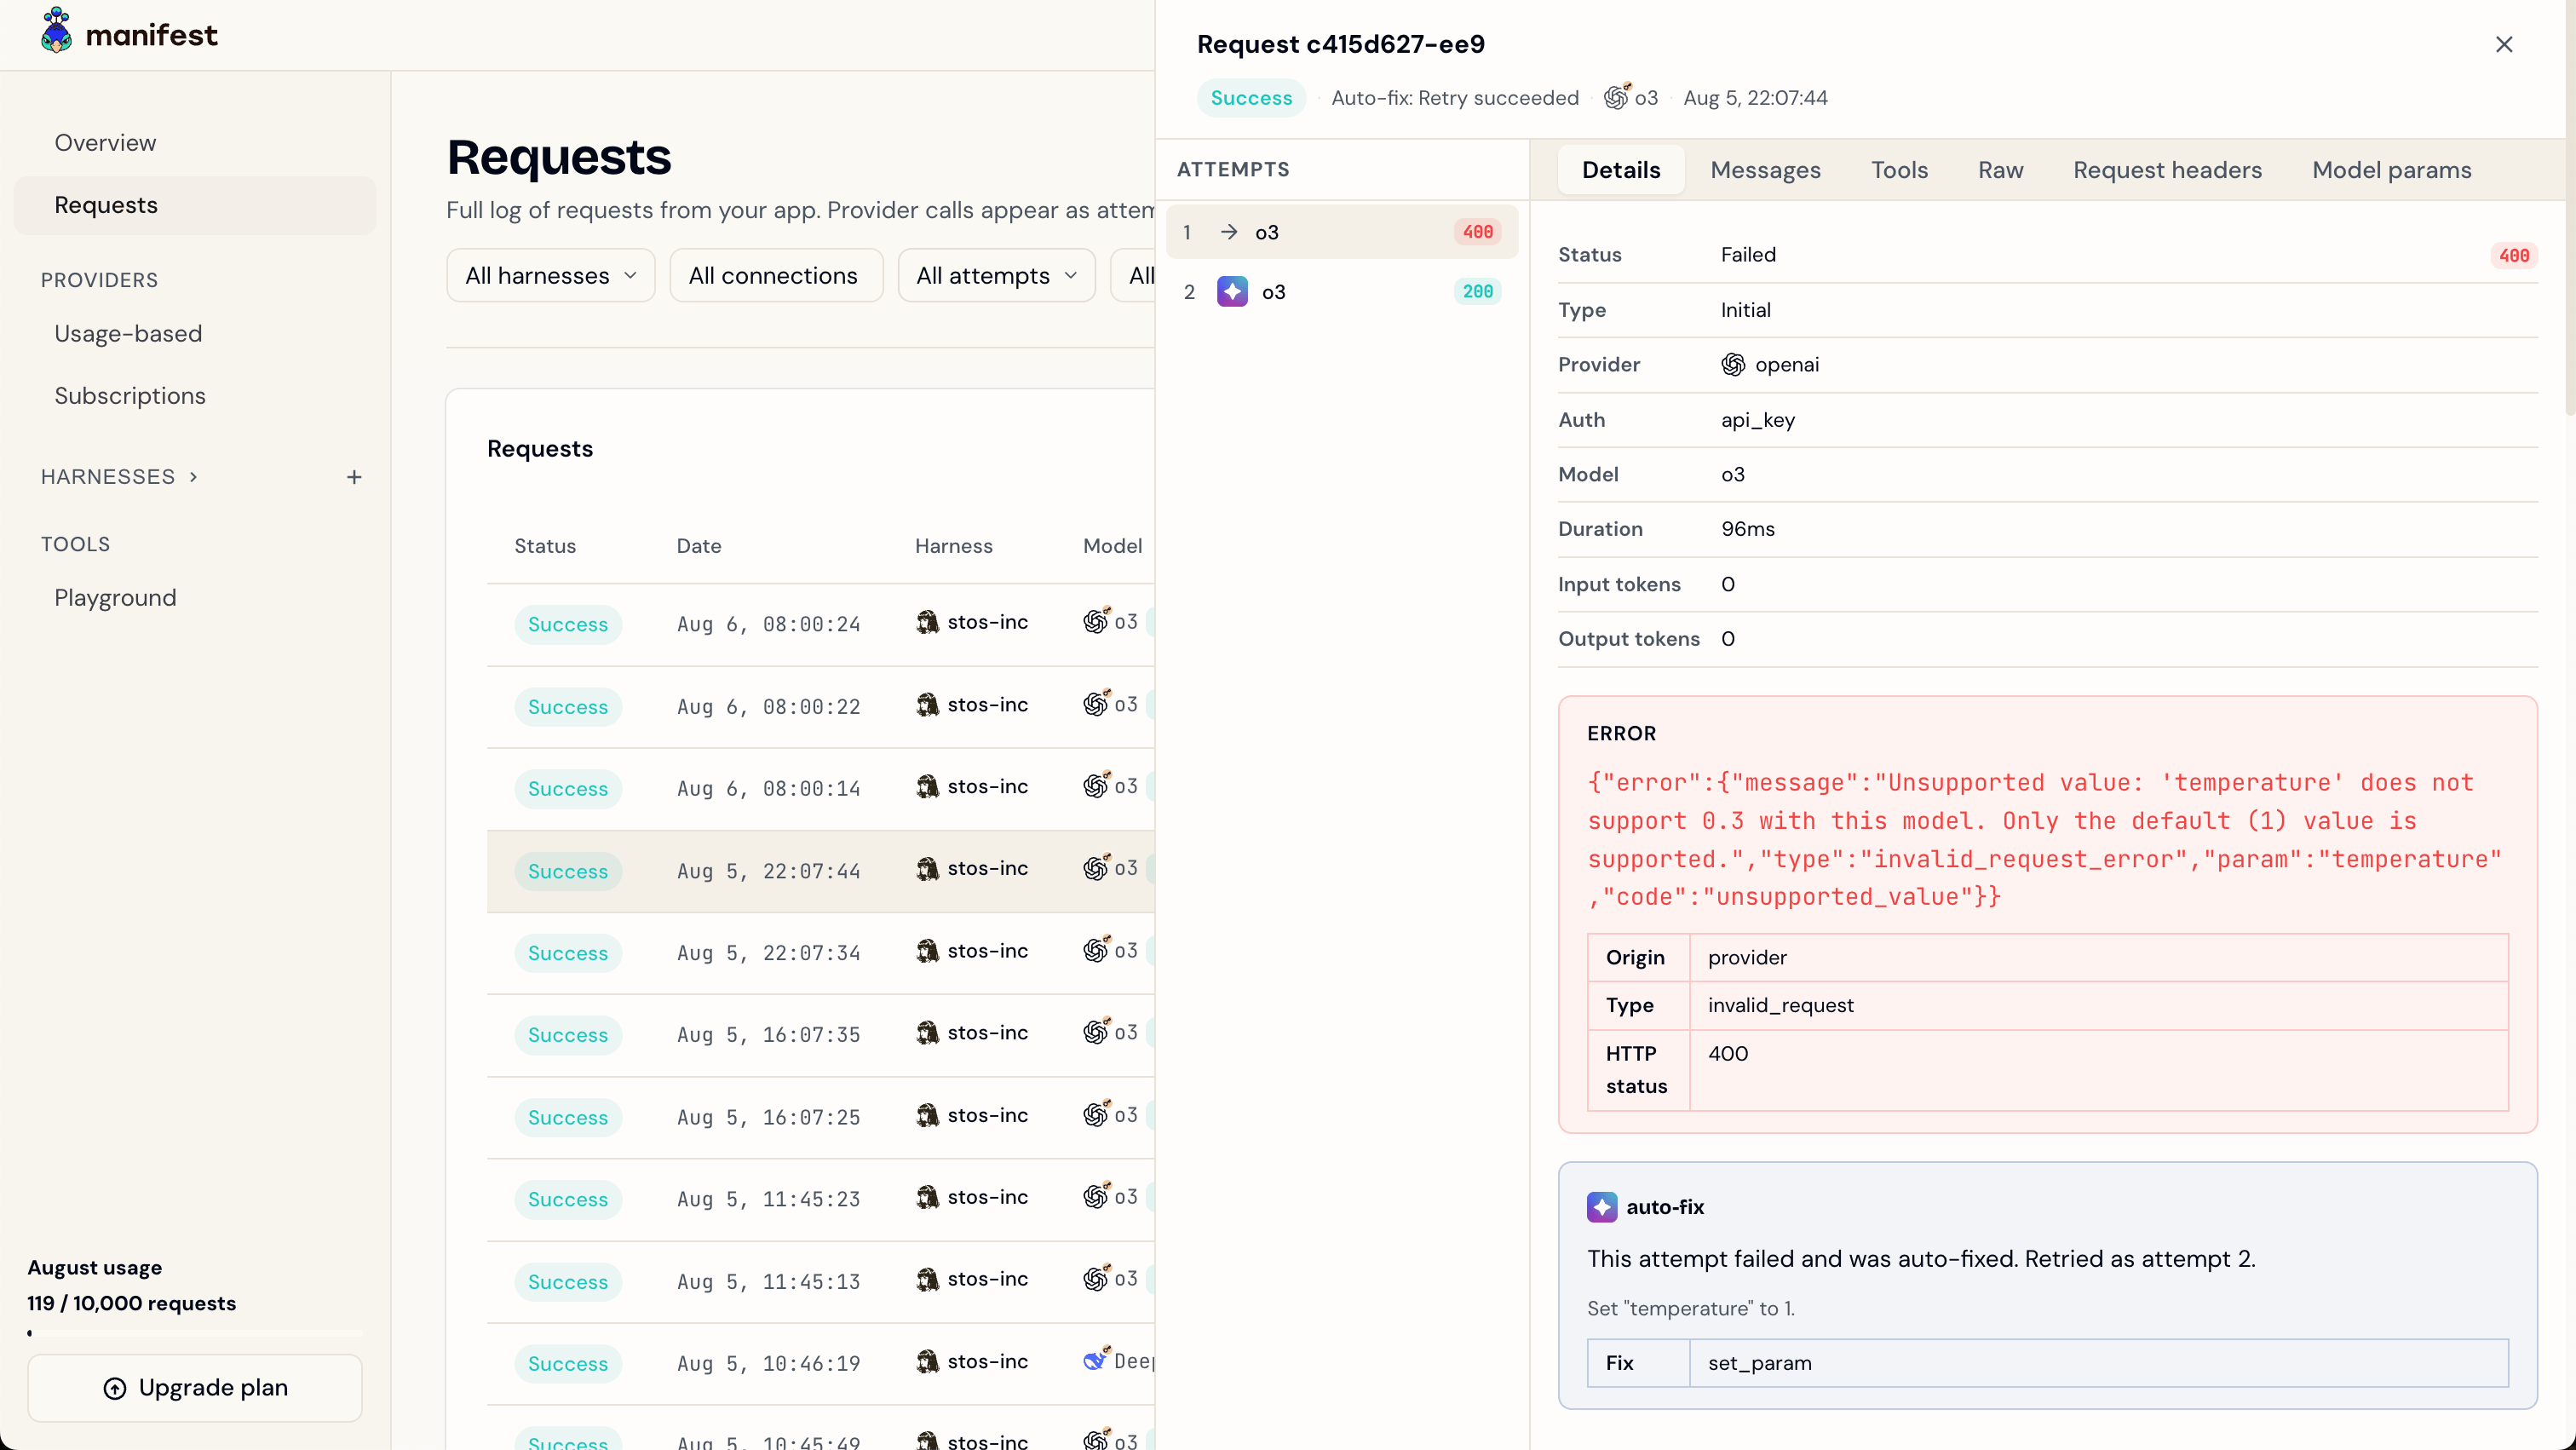
A request with two attempts: the failed call and its Autofix retry, each with its own tabs.
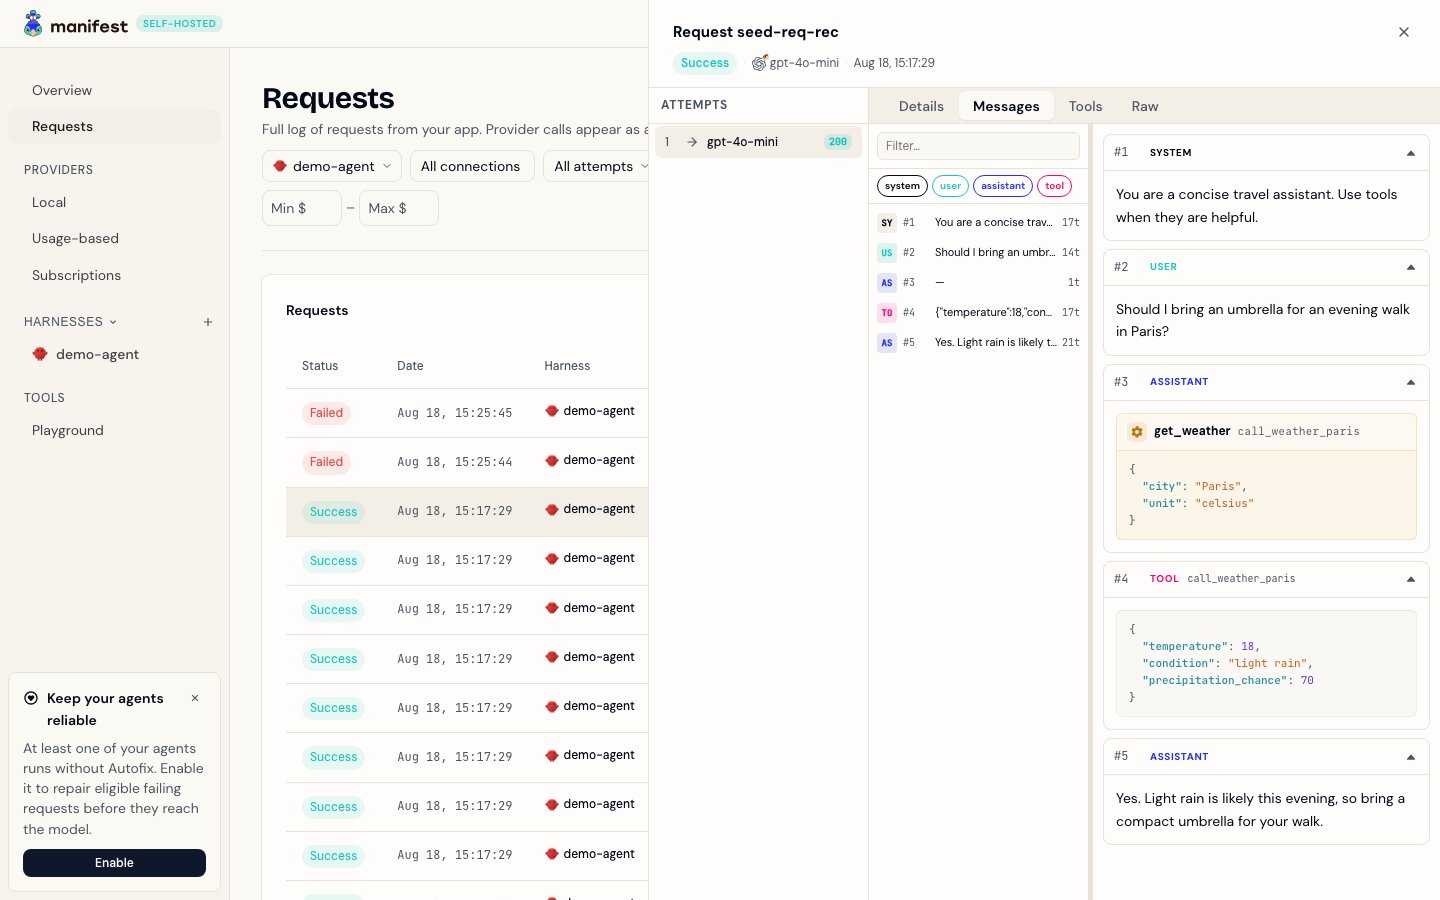
The Messages tab: the turn rail with its role filters, and the conversation in the main pane.
Turning it on
The switch is Enable logs, in the Logs section of each harness’s Settings page. New harnesses have it on. To make sure a harness records its logs, check Settings → Logs.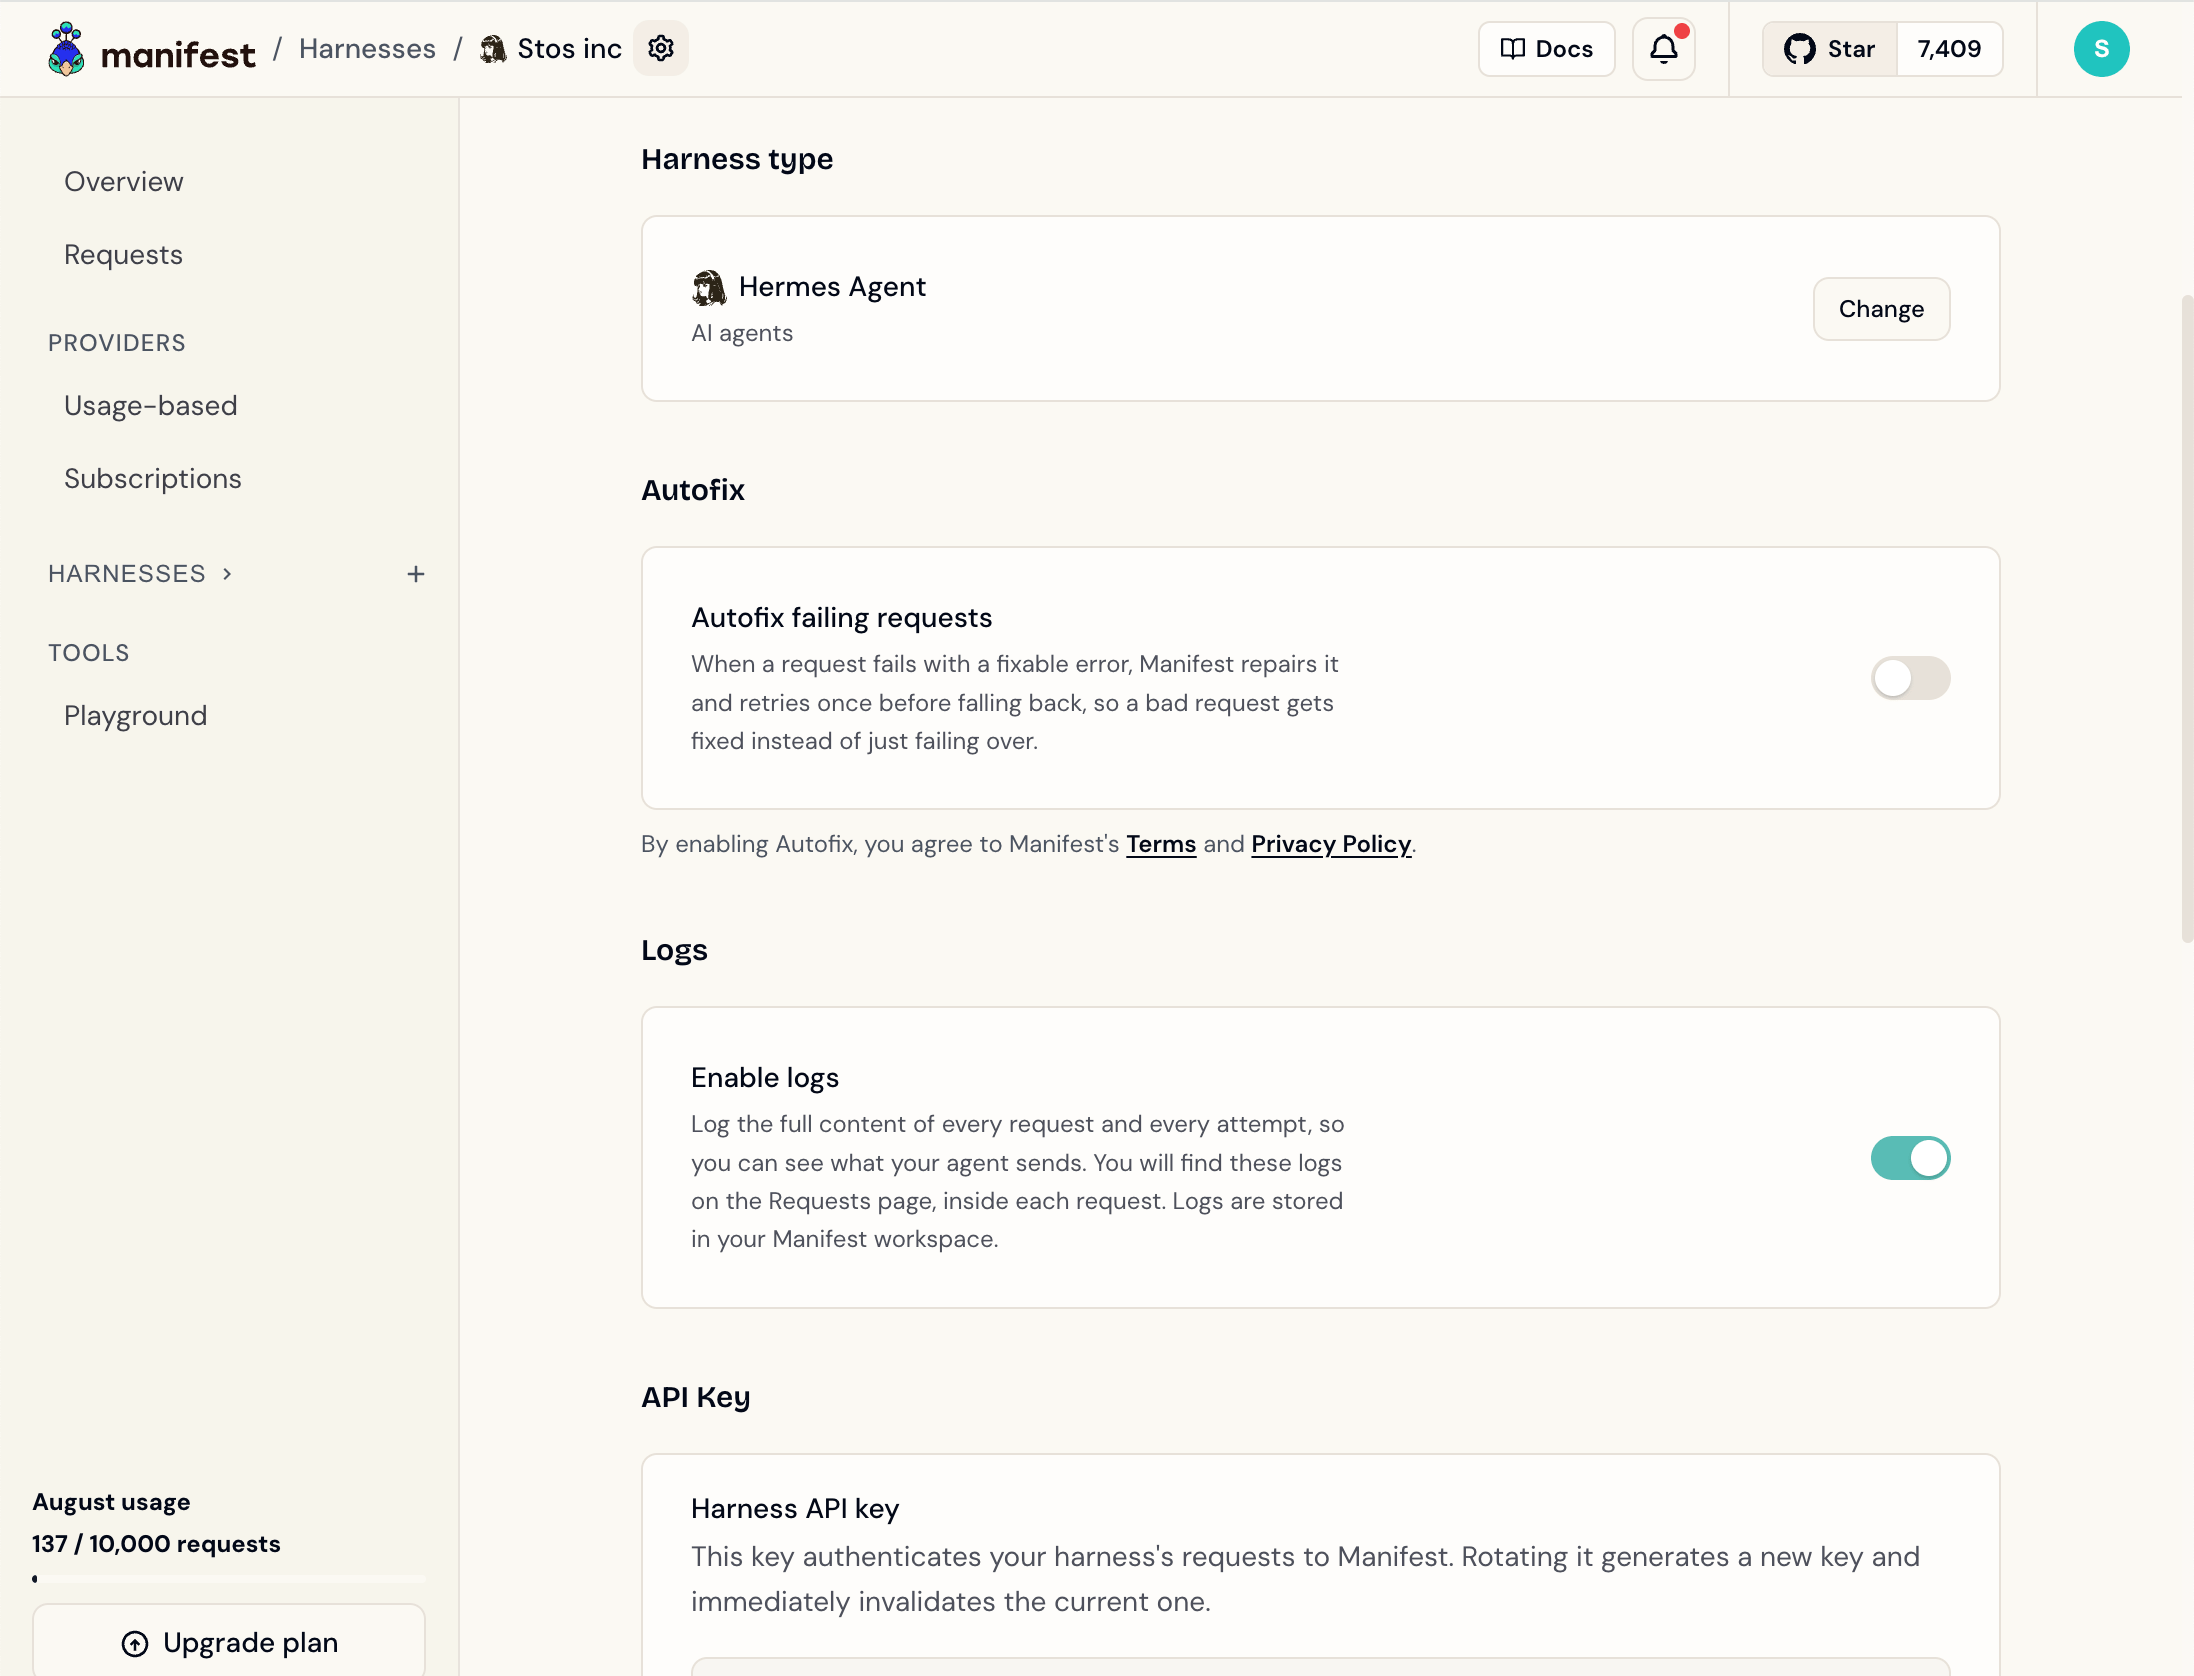
The Logs section on a harness's Settings page.
Recording stores your prompts and completions. Everything else Manifest keeps
is metadata (Data and telemetry covers the
distinction). If a harness handles data you’d rather Manifest never hold onto,
leave recording off for that harness.
Retention
Recordings are deleted on a schedule. The metadata row in the request log stays; only the stored body pair goes away.
Cloud Pro keeps 365 days only while the subscription is active or in a trial. A canceled workspace, or one whose payment failed, drops to 7 days, and the nightly cleanup applies that on its next run, deleting everything older than 7 days.
Self-hosted installs can override this with
REQUEST_RECORDING_RETENTION_DAYS. Setting it also overrides the per-plan split, so every recording on the instance expires on the same schedule.
Self-hosted storage
Logs were reintroduced in v6.18.0. On an older self-hosted install,
upgrade Manifest first.
- Docker (default)
- S3-compatible
The bundled compose file mounts a named volume
manifest_request_recordings
at /data/request-recordings and points Manifest at it. Nothing to
configure when your compose file includes that volume; an install from
before v6.18.0 needs one upgrade step first. The
volume survives docker compose down the same way the Postgres volume
does.REQUEST_RECORDING_STORAGE defaults to auto, which picks the backend by what you’ve configured: any S3 setting present means S3, otherwise the mounted filesystem path. Set it to s3, filesystem, or disabled to decide explicitly.
Full variable list: Environment variables.
Check it’s working
A storage problem never stops traffic, and the dashboard never mentions it. Flipping Enable logs on still confirms the change, and attempts come back without Messages, Tools, or Raw tabs, exactly as if logs were off. The server output is the only place the problem shows.Request recording storage unavailable: <reason> means Manifest is storing nothing, and the reason names what to fix. No such line means the backend resolved.
Platforms without a persistent disk
The one-click templates set this up for you. Render mounts a persistent disk. Railway, Fly, AWS, and Google Cloud provision object storage during deploy. Heroku, Koyeb, and DigitalOcean collect your bucket and keys as part of template setup. On any other platform with an ephemeral filesystem, point recording at S3-compatible storage yourself, or recordings only survive until the next deploy.Related
- Observability — the request log these recordings hang off
- Autofix — comparing a failed request against its patched retry
- Data and telemetry — what Manifest stores by default
- Environment variables